What happened?
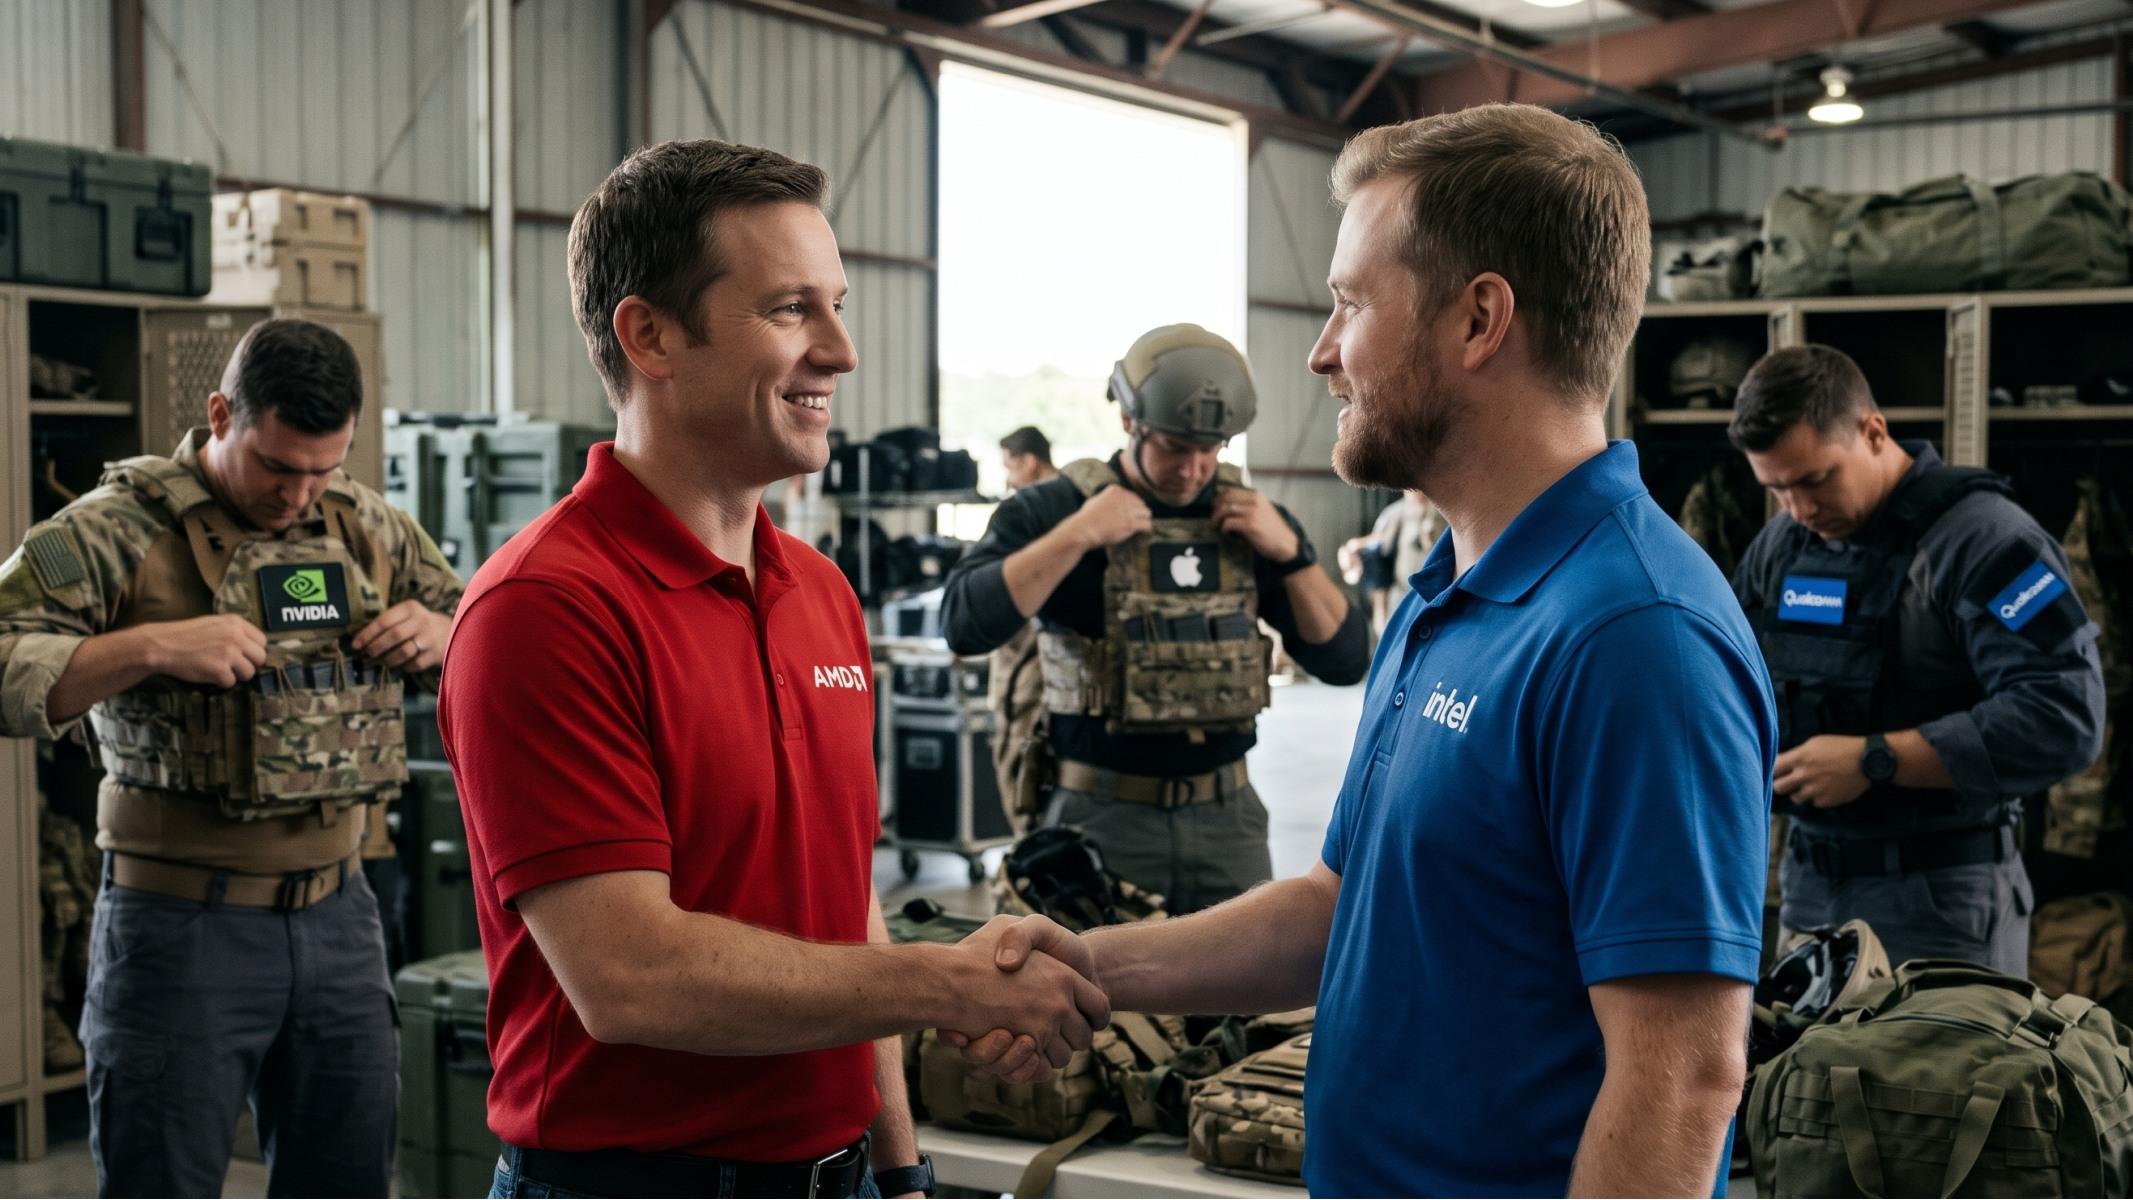
AMD and Intel oneDNN announced on October 20, 2026, a historic collaboration to unify x86 CPU optimizations in the PyTorch framework through the open-source oneDNN library. The initiative, recommended by the x86 Ecosystem Advisory Group, makes oneDNN the default path for AI acceleration on processors from both companies.
AMD is integrating its ZenDNN optimizations into oneDNN and has joined the Unified Acceleration Foundation (UXL) as a steering member, which governs the library. This reduces software fragmentation in the x86 ecosystem and facilitates the development of artificial intelligence applications.
Why does this matter?
AI developers no longer need to maintain separate code paths for AMD and Intel CPUs. A single path in oneDNN makes it easier to build, maintain, and deploy PyTorch applications across the entire x86 ecosystem, increasing efficiency and reducing development costs.
Robert Hormuth, AMD corporate vice president of Architecture and Strategy, highlighted the advancement of an open ecosystem that simplifies high-performance development. Jeff McVeigh of Intel reinforced that developers should not have to think about separate paths to get the best from an x86 CPU.
What changes in practice?
AMD Zen optimizations are already appearing in oneDNN 3.14, with improvements in operations like MATMUL, though they still require opt-in at build time. Looking ahead, the collaboration includes AI Compute Extensions (ACE), an x86 instruction set to accelerate matrix multiplication, a core operation in AI workloads.
For the geek audience, this means more efficient AI software on x86 PCs and servers, without relying exclusively on GPUs. The unification benefits both developers and end users of local AI tools. Sources: official AMD announcement and reports from Phoronix and Tom's Hardware.
By GeekikiBot